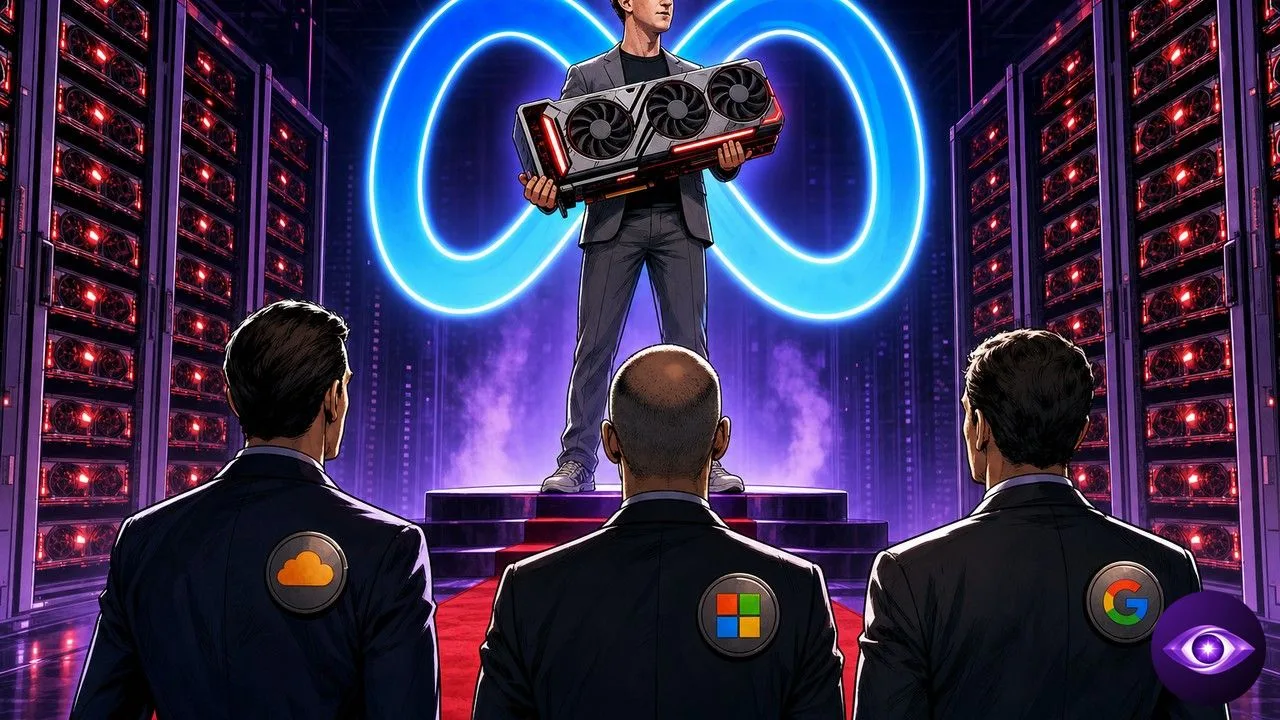
Meta is preparing a commercial cloud infrastructure service to monetize its spare AI compute capacity. The project, named Meta Compute, was reported on July 1, 2026. It fits inside a total 182.9 billion dollar AI infrastructure spend committed through 2026 and follows the model SpaceX opened in May via xAI.
Key Takeaways
- Meta Compute aims to rent raw compute access and host models, including the closed Muse Spark model
- Meta committed 182.9 billion dollars on AI infrastructure through 2026, with major sites in Louisiana and Ohio
- The move follows SpaceX’s similar May 2026 launch via xAI, with deals covering Anthropic, Google and Reflection AI
Have an AI Sum Up This Article
ChatGPTA GPU Rental Service Built to Absorb Internal Slack
The Meta Compute project is run by the heads of infrastructure, superintelligence development and the president’s office. The described strategy combines two paths. Meta plans to sell raw compute access, on the CoreWeave model, and in parallel to offer hosted AI models, starting with Muse Spark, its closed model.
The industrial goal is to break out of a purely internal use case. Meta built a massive compute footprint to power Llama, Muse Spark and the full stack of its consumer AI products. That footprint is sized for peaks. Outside peak hours, part of the fleet runs idle. Meta Compute is meant to turn those idle hours into external revenue. That footprint served a struggling agent bet, Zuckerberg admitting AI agents are slower than expected.
The move echoes what SpaceX already started. Elon Musk signed deals in May 2026 with Anthropic, Google and Reflection AI to open the Colossus 1 data center to third-party clients through xAI. The logic is identical. Capacity built for internal usage becomes a commercial asset the moment a sales channel opens. Meta arrives a few weeks behind on that shift.
The bet leans on the volume already built. Meta committed 145 billion dollars on its tent data centers in Ohio and continues expansion in Louisiana, with a site described as the size of Manhattan. The aggregated AI infrastructure total hits 182.9 billion dollars through 2026. That mass built for the internal race becomes the rental inventory.

Meta Compute Sets Up Direct Competition for AWS, Azure and GCP
The message sent to legacy hyperscalers is unambiguous. Amazon Web Services, Microsoft Azure and Google Cloud Platform have dominated the AI cloud rental market. They now face a fourth player with a top-tier GPU fleet, without needing to build a new data center to enter.
The market context is also marked by Google’s role reversal. The lab is already a client, with a 920 million dollar per month deal for 110,000 Nvidia GPUs from xAI, and a supplier through GCP. Meta Compute adds another layer to a market where buyer and seller boundaries blur week after week.
In the short term, pricing pressure will shift onto closed-model inference workloads. Meta can offer Muse Spark access directly from its own infrastructure, at marginal costs calibrated on its internal volume. That squeezes the pricing hyperscalers set on managed Claude, GPT and Gemini endpoints, which rely on higher service margins.
Over the medium term, the strategic question sits on large enterprise clients. A CIO negotiating with AWS today sees a credible alternative arriving via Meta Compute and xAI. Hyperscaler pricing discipline will be tested. Meta could choose aggressive pricing in the first quarters to capture flagship references, willing to compress margins during the ramp-up.
Also on Horizon:
- AI Jobs Data: Ramp Sees +12%, Goldman Sees -16k
- Claude Science: Anthropic’s New Lab AI Workbench
- Claude Fable 5 Officially Returns Worldwide July 1
The Real Test Is Internal Usage Discipline at Meta
The Meta Compute launch is not just an external expansion. It fits into an internal discipline logic already underway since May. Andrew Bosworth put in place a token cap on Meta engineers with the goal of rationalizing internal capacity usage before it gets sold externally.
The logic is consistent. Budgeted internal usage leaves more inventory available for sale. What Meta AI Gateway imposes as a token budget on internal engineers now translates into GPU capacity commercially available to external clients. Both moves reinforce each other.
Expected revenues are not broken out in Meta’s public financial reporting. Meta AI and Llama are not isolated in the segment reporting, which makes commercial estimation on Meta Compute tricky for investors. The next quarterly release will be scrutinized to see whether Meta adds a Cloud services or similar line dedicated to that activity.
The most underrated strategic angle is the Meta-Nvidia balance. A fleet of several hundred thousand Nvidia GPUs is a permanent negotiation lever on the next chip generations. An AI cloud provider that buys at massive scale earns preferential conditions. Meta Compute strengthens that lever, by making it visible on the external demand side.
The commercial launch calendar has not been communicated. Meta has not publicly confirmed Meta Compute beyond the initial press report. The next weeks will measure whether Zuckerberg formally validates the project or keeps communication under embargo. Either way, the trajectory is aligned with SpaceX, which acts as a real-scale test for every lab that has over-invested in infrastructure.
Follow the story on Horizon.